About
I am a Research Fellow and final-year PhD candidate at the University of Sheffield (Sheffield NLP Group), focusing on cross-lingual adaptation, model compression, and resource-efficient language modeling. I have over 7 years of combined academic and industry experience in NLP, including R&D roles at Hitachi, Ltd. (Japan) and AstraZeneca (UK). My research has been published at top-tier venues such as ACL, EMNLP, EACL, TMLR, and Computational Linguistics, receiving a COLM 2026 Outstanding Paper Award. Beyond research, I actively contribute to the NLP community as an ARR Support Team member and EACL 2026 SRW Co-Chair.
I am planning to submit my thesis before March 2027 and am officially entering the job market!
I am primarily seeking Faculty positions starting April 2027 or before. I am also open to Research Fellow or Research Scientist roles. If you know of any opportunities or have suggestions, please contact me at ayamaguchi1@sheffield.ac.uk.
News
-
I'm starting as a Research Fellow at the University of Sheffield today!
-
Our COLM 2026 paper, "How Can We Synthesize High-Quality Pretraining Data? A Systematic Study of Prompt Design, Generator Model, and Source Data", has been awarded the Outstanding Paper Award 🏆! The link to the paper is here.
-
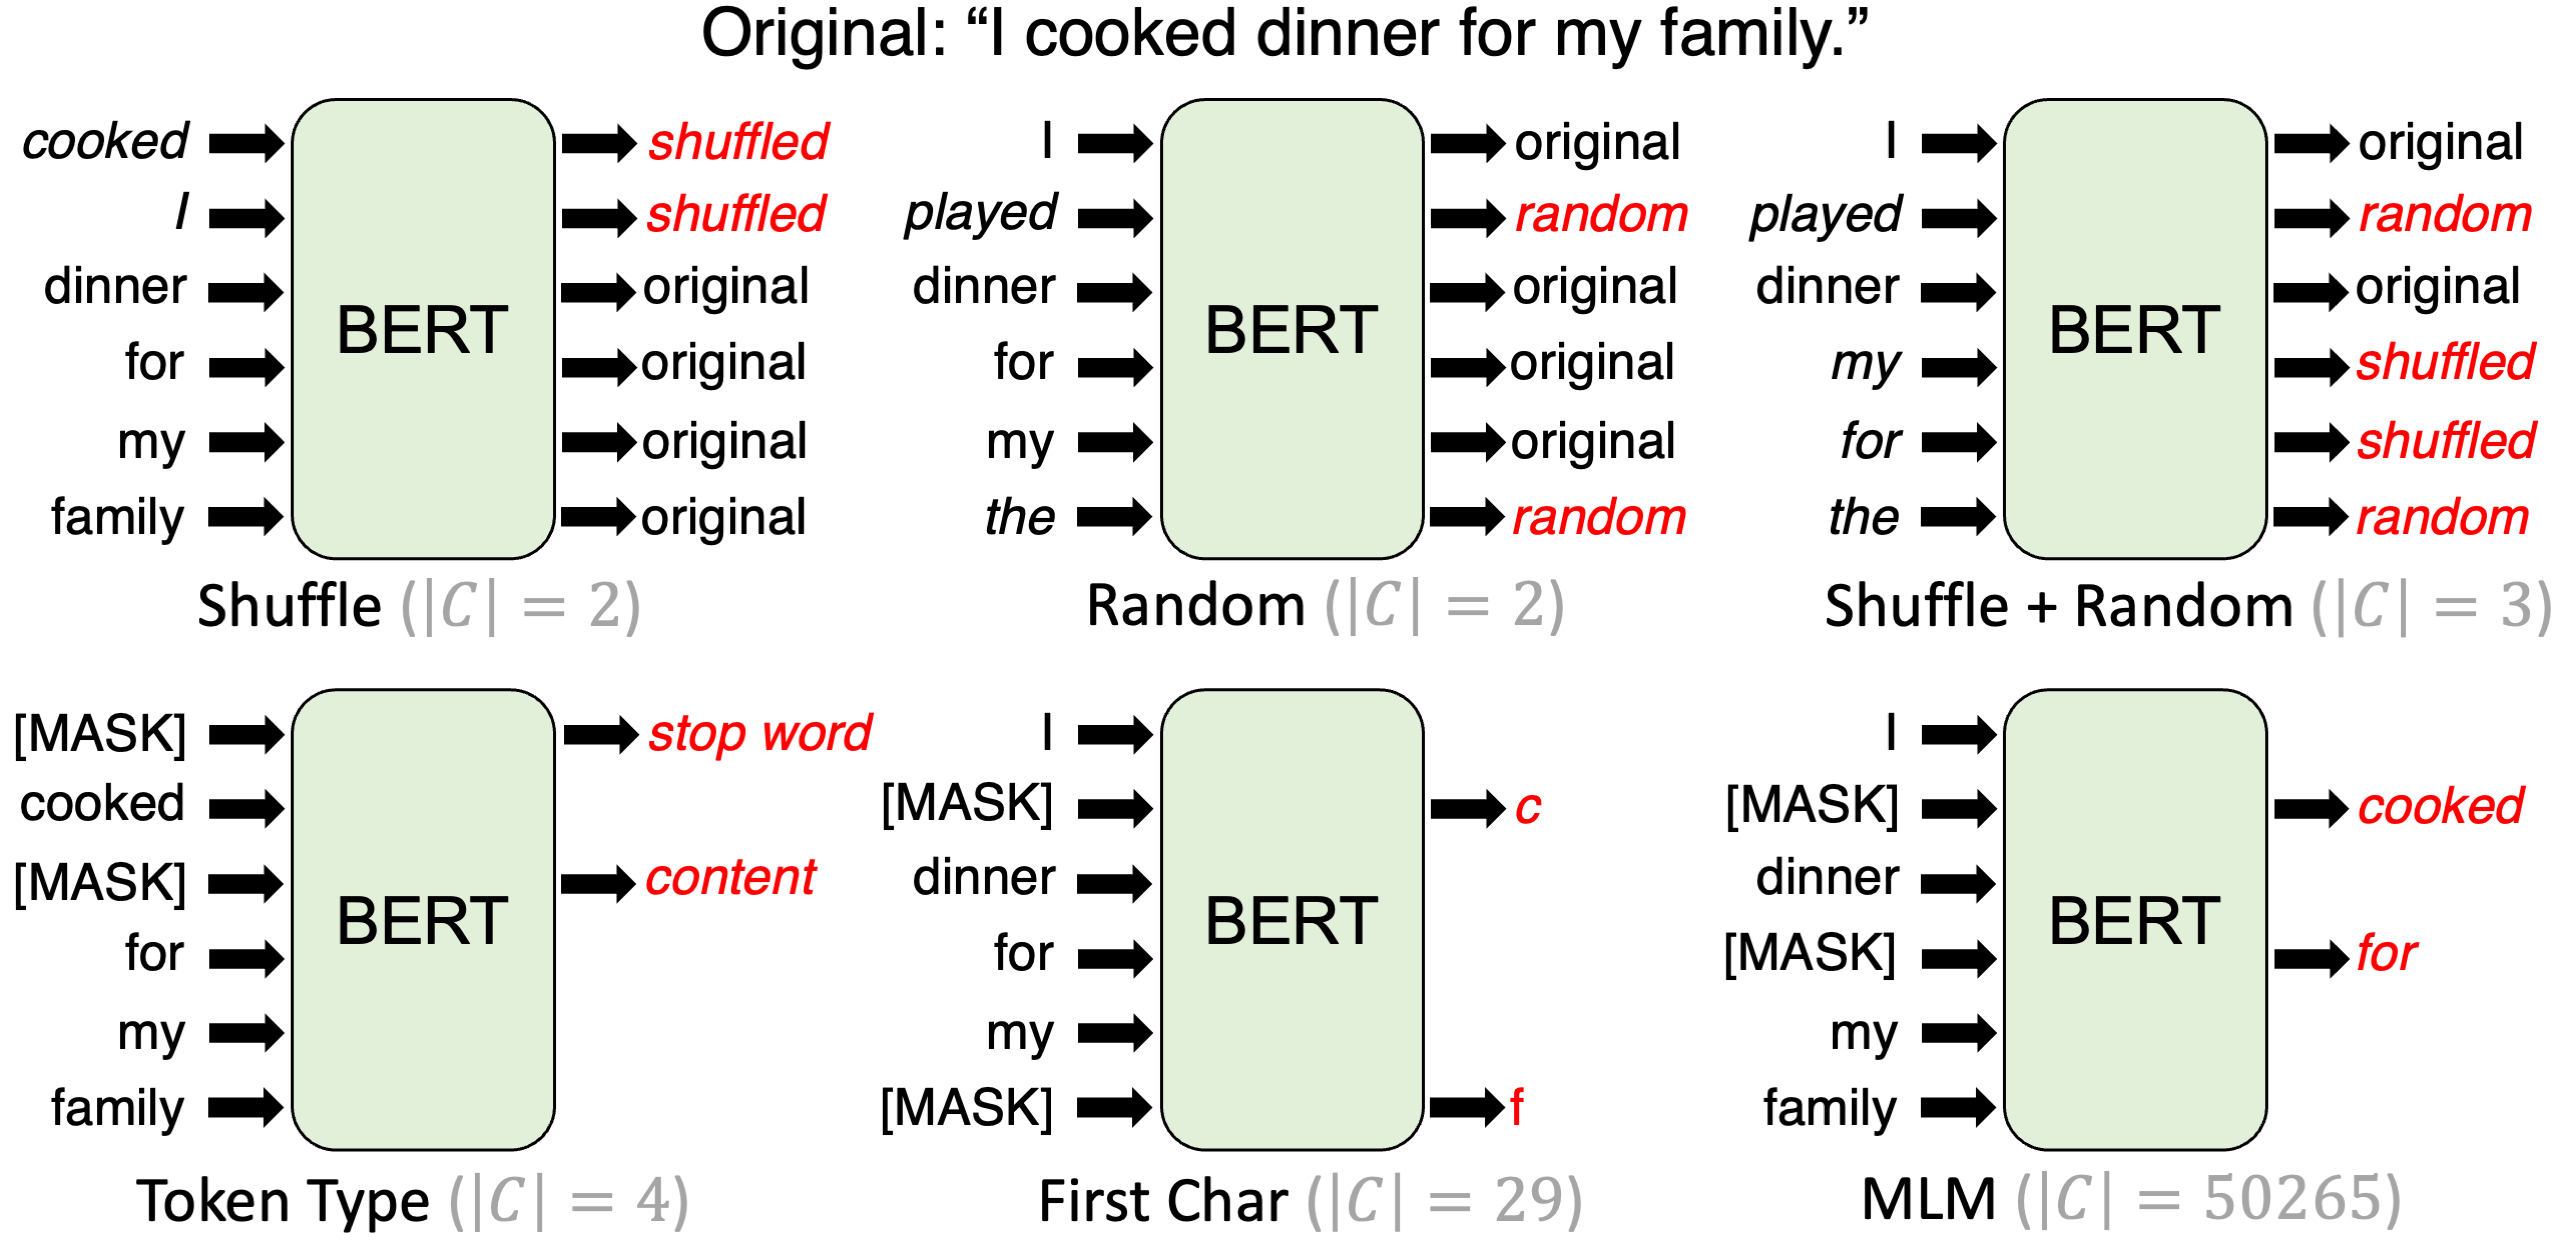
My last piece of PhD research, "Synthetic Pre-pretraining Survives Scale, but Not as a Grammatical Prior", is out as a preprint on arXiv! See here for details. This is the largest ever study on synthetic pre-pretraining, which is a promising approach to improve token efficiency of pre-training.
-
One co-authored paper, "When Tokenizers Fail: Byte-Level Chunking for Zero-Shot Transfer to Low-Resource Languages", has been accepted to EMNLP 2026 (Main)!
-
One co-authored paper, "MultiHashFormer: Hash-based Generative Language Models", has been accepted to EMNLP 2026 (Main)! See here for the preprint.
-
One co-authored paper, "How Can We Synthesize High-Quality Pretraining Data? A Systematic Study of Prompt Design, Generator Model, and Source Data", has been accepted to COLM 2026!
-
One co-authored paper, "MultiHashFormer: Hash-based Generative Language Models", has been out as a preprint on arXiv! See here. This is an exciting study on new hash-based generative language models that can perform well on various tasks.
-
I gave an invited talk at the NLIP Seminar Series, University of Cambridge! See here for the slides.
-
One co-authored paper, "How Can We Synthesize High-Quality Pretraining Data? A Systematic Study of Prompt Design, Generator Model, and Source Data", has been out as a preprint on arXiv! See here.
-
One co-authored paper, "Examining the Idiomaticity Decomposability Hypothesis", has been accepted to ACL 2026!
-
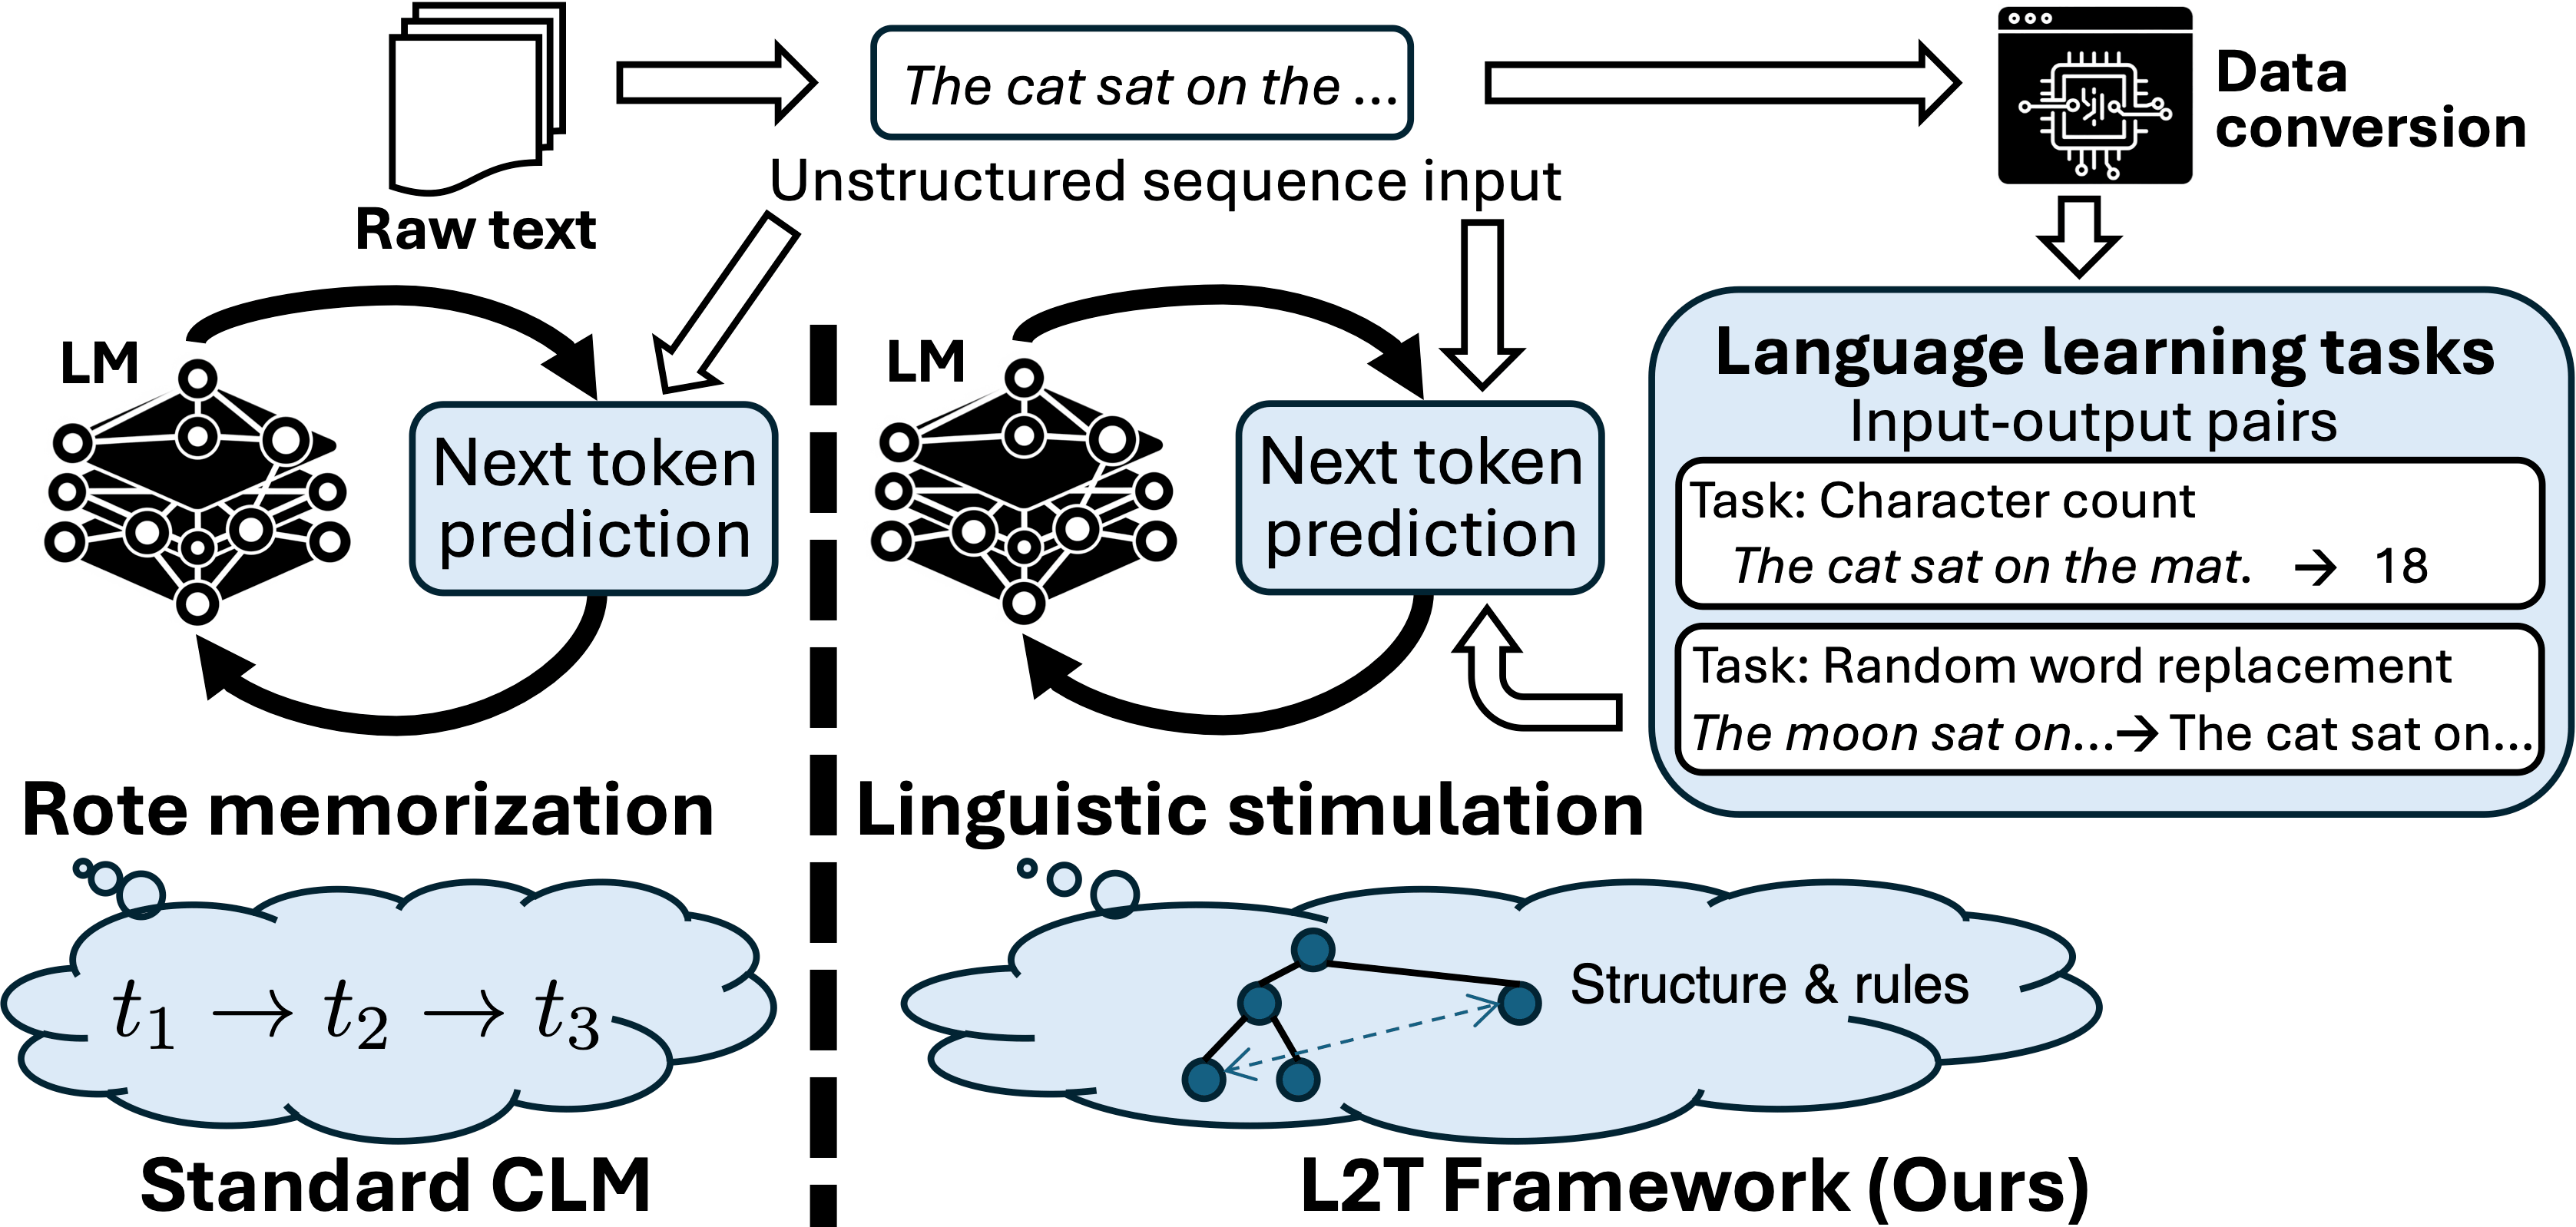
Our paper on enhancing linguistic competence of language models through pre-training with language learning tasks has been accepted to ACL 2026! See here for the preprint.
-
Our paper on mitigating catastrophic forgetting in target language adaptation of LLMs has been accepted to ACL 2026! See here for the preprint.
-
Our paper on extremely low-resource vocabulary expansion has been accepted to Computational Linguistics! See here for the preprint.
-
Our paper on vocabulary expansion of chat models has been accepted to Transactions on Machine Learning Research (TMLR)! See here.
-
I will be co-chairing the EACL 2026 Student Research Workshop. Call for papers will be out soon!
-
Updated CV. See here.
Research Interests
Cross-lingual Transfer, Efficient Language Modelling, Natural Language Understanding, Natural Language Processing, Machine Learning
Recent Work
Towards efficient and fair natural language processing across languages
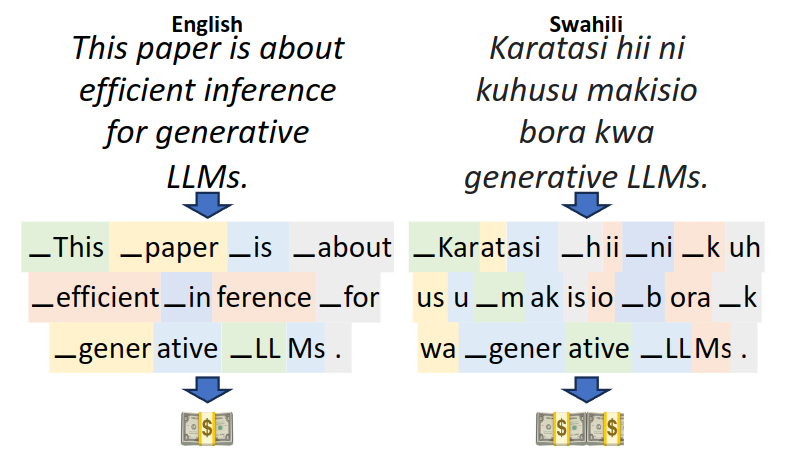
Explore efficient pretraining methods for language models
Links
Contact
You can send me messages via this contact form.